Step-Audio 2 Technical Report
This paper presents Step-Audio 2, an end-to-end multi-modal large language model designed for industry-strength audio understanding and speech conversation. By integrating a latent audio encoder and reasoning-centric reinforcement learning (RL), Step-Audio 2 achieves promising performance in automatic speech recognition (ASR) and audio understanding. To facilitate genuine end-to-end speech convers
Pisets: A Robust Speech Recognition System for Lectures and Interviews
This work presents a speech-to-text system "Pisets" for scientists and journalists which is based on a three-component architecture aimed at improving speech recognition accuracy while minimizing errors and hallucinations associated with the Whisper model. The architecture comprises primary recognition using Wav2Vec2, false positive filtering via the Audio Spectrogram Transformer (AST), and final
TeleAntiFraud-28k: An Audio-Text Slow-Thinking Dataset for Telecom Fraud Detection
The detection of telecom fraud faces significant challenges due to the lack of high-quality multimodal training data that integrates audio signals with reasoning-oriented textual analysis. To address this gap, we present TeleAntiFraud-28k, the first open-source audio-text slow-thinking dataset specifically designed for automated telecom fraud analysis. Our dataset is constructed through three stra
The Devil behind the mask: An emergent safety vulnerability of Diffusion LLMs
Diffusion-based large language models (dLLMs) have recently emerged as a powerful alternative to autoregressive LLMs, offering faster inference and greater interactivity via parallel decoding and bidirectional modeling. However, despite strong performance in code generation and text infilling, we identify a fundamental safety concern: existing alignment mechanisms fail to safeguard dLLMs against c
RL Is a Hammer and LLMs Are Nails: A Simple Reinforcement Learning Recipe for Strong Prompt Injection
Prompt injection poses a serious threat to the reliability and safety of LLM agents. Recent defenses against prompt injection, such as Instruction Hierarchy and SecAlign, have shown notable robustness against static attacks. However, to more thoroughly evaluate the robustness of these defenses, it is arguably necessary to employ strong attacks such as automated red-teaming. To this end, we introdu
System Report for CCL25-Eval Task 10: SRAG-MAV for Fine-Grained Chinese Hate Speech Recognition
This paper presents our system for CCL25-Eval Task 10, addressing Fine-Grained Chinese Hate Speech Recognition (FGCHSR). We propose a novel SRAG-MAV framework that synergistically integrates task reformulation(TR), Self-Retrieval-Augmented Generation (SRAG), and Multi-Round Accumulative Voting (MAV). Our method reformulates the quadruplet extraction task into triplet extraction, uses dynamic retri
Voxlect: A Speech Foundation Model Benchmark for Modeling Dialects and Regional Languages Around the Globe
We present Voxlect, a novel benchmark for modeling dialects and regional languages worldwide using speech foundation models. Specifically, we report comprehensive benchmark evaluations on dialects and regional language varieties in English, Arabic, Mandarin and Cantonese, Tibetan, Indic languages, Thai, Spanish, French, German, Brazilian Portuguese, and Italian. Our study used over 2 million train
Latent Speech-Text Transformer
Auto-regressive speech-text models pre-trained on interleaved text tokens and discretized speech tokens demonstrate strong speech understanding and generation, yet remain substantially less compute-efficient than text LLMs, partly due to the much longer sequences of speech tokens relative to text. This modality imbalance disproportionately allocates pre-training and inference compute to speech, po
MoST: Mixing Speech and Text with Modality-Aware Mixture of Experts
We present MoST (Mixture of Speech and Text), a novel multimodal large language model that seamlessly integrates speech and text processing through our proposed Modality-Aware Mixture of Experts (MAMoE) architecture. While current multimodal models typically process diverse modality representations with identical parameters, disregarding their inherent representational differences, we introduce sp
Whisfusion: Parallel ASR Decoding with Masked Diffusion
Autoregressive (AR) encoder-decoder models dominate high-quality multilingual ASR, but their left-to-right decoders make inference latency scale with transcript length. A natural alternative, CTC-style non-autoregressive (NAR) systems avoid this bottleneck but their conditional independence assumption sacrifices transcript-level generative modeling. Masked diffusion language models (e.g., LLaDA, M
Visual Contextual Attack: Jailbreaking MLLMs with Image-Driven Context Injection
With the emergence of strong vision language capabilities, multimodal large language models (MLLMs) have demonstrated tremendous potential for real-world applications. However, the security vulnerabilities exhibited by the visual modality pose significant challenges to deploying such models in open-world environments. Recent studies have successfully induced harmful responses from target MLLMs by
AdvAD: Exploring Non-Parametric Diffusion for Imperceptible Adversarial Attacks
Imperceptible adversarial attacks aim to fool DNNs by adding imperceptible perturbation to the input data. Previous methods typically improve the imperceptibility of attacks by integrating common attack paradigms with specifically designed perception-based losses or the capabilities of generative models. In this paper, we propose Adversarial Attacks in Diffusion (AdvAD), a novel modeling framework
MCAT: Scaling Many-to-Many Speech-to-Text Translation with MLLMs to 70 Languages
Multimodal Large Language Models (MLLMs) have achieved great success in Speech-to-Text Translation (S2TT) tasks. However, current research is constrained by two key challenges: language coverage and efficiency. Most of the popular S2TT datasets are substantially English-centric, which restricts the scaling-up of MLLMs' many-to-many translation capabilities. Moreover, the inference speed of MLLMs d
STAR: A Benchmark for Astronomical Star Fields Super-Resolution
Super-resolution (SR) advances astronomical imaging by enabling cost-effective high-resolution capture, crucial for detecting faraway celestial objects and precise structural analysis. However, existing datasets for astronomical SR (ASR) exhibit three critical limitations: flux inconsistency, object-crop setting, and insufficient data diversity, significantly impeding ASR development. We propose S
OpenSTBench: Beyond Semantic Evaluation for Speech Translation
Speech translation systems increasingly span speech-to-text translation (S2TT), speech-to-speech translation (S2ST), offline translation, and streaming generation, producing outputs that differ in modality, speech realization, and timing behavior. Existing evaluation practices assess important aspects such as translation quality, speech quality, and temporal quality, but these aspects are often ev

FinVault: Benchmarking Financial Agent Safety in Execution-Grounded Environments
Financial agents powered by large language models (LLMs) are increasingly deployed for investment analysis, risk assessment, and automated decision-making, where their abilities to plan, invoke tools, and manipulate mutable state introduce new security risks in high-stakes and highly regulated financial environments. However, existing safety evaluations largely focus on language-model-level conten
Siren: A Learning-Based Multi-Turn Attack Framework for Simulating Real-World Human Jailbreak Behaviors
Large language models (LLMs) are widely used in real-world applications, raising concerns about their safety and trustworthiness. While red-teaming with jailbreak prompts exposes the vulnerabilities of LLMs, current efforts focus primarily on single-turn attacks, overlooking the multi-turn strategies used by real-world adversaries. Existing multi-turn methods rely on static patterns or predefined
RelayS2S: A Dual-Path Speculative Generation for Real-Time Dialogue
Real-time spoken dialogue systems face a fundamental tension between latency and response quality. End-to-end speech-to-speech (S2S) models respond immediately and naturally handle turn-taking, backchanneling, and interruption, but produce semantically weaker outputs. Cascaded pipelines (ASR -> LLM) deliver stronger responses at the cost of latency that grows with model size. We present RelayS2S,
Lifelong Safety Alignment for Language Models
LLMs have made impressive progress, but their growing capabilities also expose them to highly flexible jailbreaking attacks designed to bypass safety alignment. While many existing defenses focus on known types of attacks, it is more critical to prepare LLMs for unseen attacks that may arise during deployment. To address this, we propose a lifelong safety alignment framework that enables LLMs to c
MURMUR: An Efficient Inference System for Long-Form ASR
Long-form automatic speech recognition (ASR) requires both high accuracy and low latency, but existing systems force a trade-off between the two. Chunk-based pipelines process audio in parallel windows for low latency, but lose cross-chunk context and need brittle heuristics to align speakers and timestamps at boundaries. Long-context ASR models resolve everything in a single pass for better accur
Two Heads Are Better Than One: Audio-Visual Speech Error Correction with Dual Hypotheses
This paper introduces a new paradigm for generative error correction (GER) framework in audio-visual speech recognition (AVSR) that reasons over modality-specific evidences directly in the language space. Our framework, DualHyp, empowers a large language model (LLM) to compose independent N-best hypotheses from separate automatic speech recognition (ASR) and visual speech recognition (VSR) models.
MixAT: Combining Continuous and Discrete Adversarial Training for LLMs
Despite recent efforts in Large Language Model (LLM) safety and alignment, current adversarial attacks on frontier LLMs can still consistently force harmful generations. Although adversarial training has been widely studied and shown to significantly improve the robustness of traditional machine learning models, its strengths and weaknesses in the context of LLMs are less understood. Specifically,
DMSC: Dynamic Multi-Scale Coordination Framework for Time Series Forecasting
Time Series Forecasting (TSF) faces persistent challenges in modeling intricate temporal dependencies across different scales. Despite recent advances leveraging different decomposition operations and novel architectures based on CNN, MLP or Transformer, existing methods still struggle with static decomposition strategies, fragmented dependency modeling, and inflexible fusion mechanisms, limiting
ICON: Intent-Context Coupling for Efficient Multi-Turn Jailbreak Attack
Multi-turn jailbreak attacks have emerged as a critical threat to Large Language Models (LLMs), bypassing safety mechanisms by progressively constructing adversarial contexts from scratch and incrementally refining prompts. However, existing methods suffer from the inefficiency of incremental context construction that requires step-by-step LLM interaction, and often stagnate in suboptimal regions
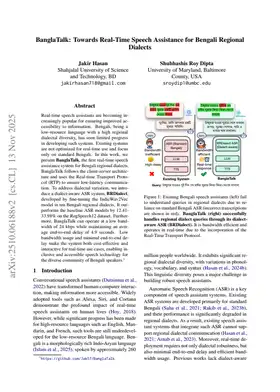
BanglaTalk: Towards Real-Time Speech Assistance for Bengali Regional Dialects
Real-time speech assistants are becoming increasingly popular for ensuring improved accessibility to information. Bengali, being a low-resource language with a high regional dialectal diversity, has seen limited progress in developing such systems. Existing systems are not optimized for real-time use and focus only on standard Bengali. In this work, we present BanglaTalk, the first real-time speec